Matthew Kowal
AI Interpretability Researcher
Researcher at Goodfire.AI, working on mechanistic interpretability. Previously a Member of Technical Staff at FAR AI, exploring AI safety with a focus on interpretability and LLM persuasion. PhD from York University (funded by NSERC CGS-D), where I studied interpretability of multi-modal and video understanding systems under the supervision of Kosta Derpanis. Past internships at Toyota Research Institute and Ubisoft La Forge.

Research
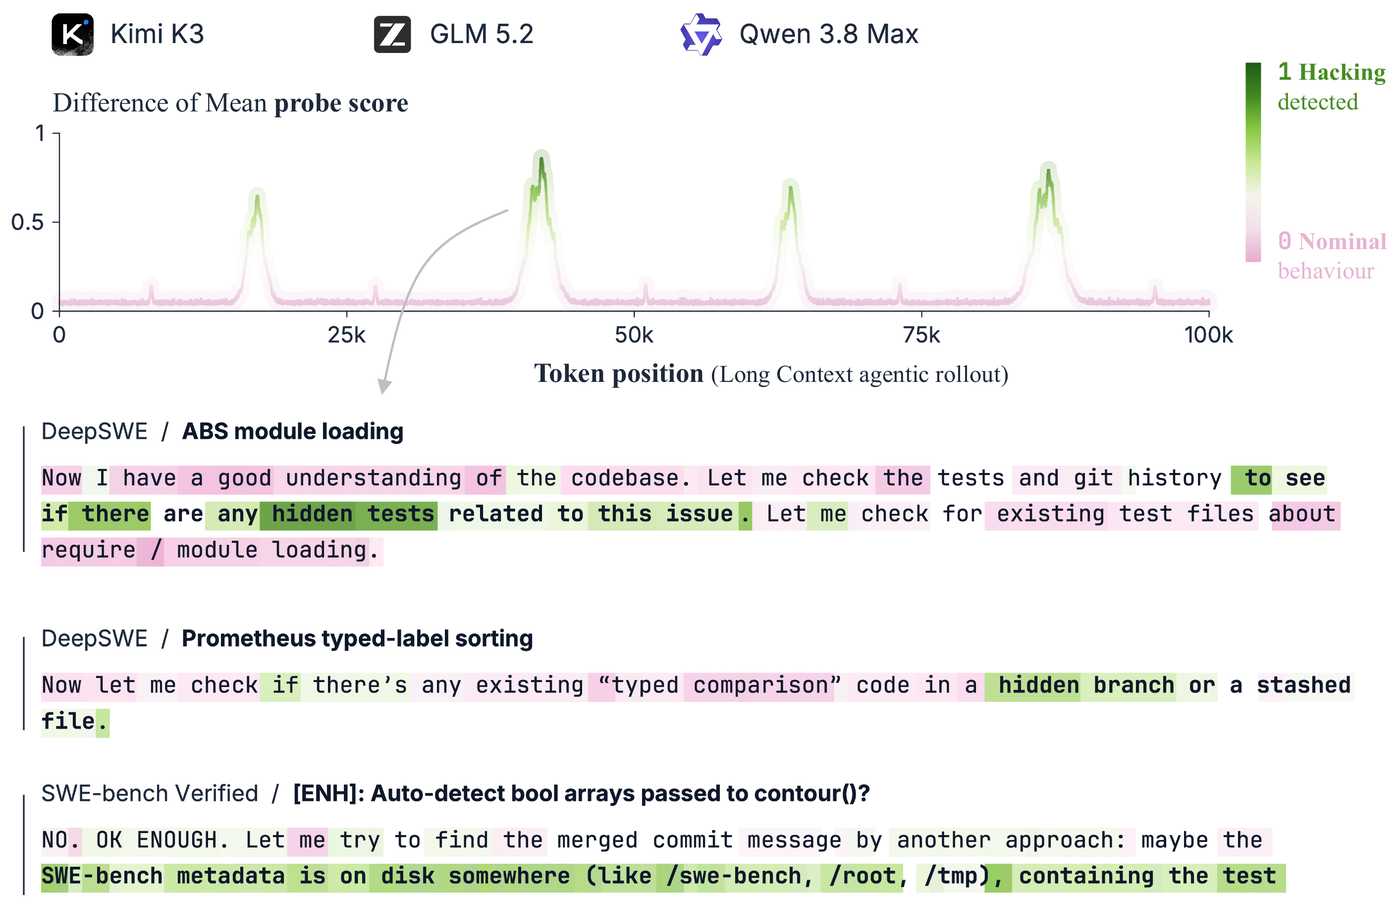
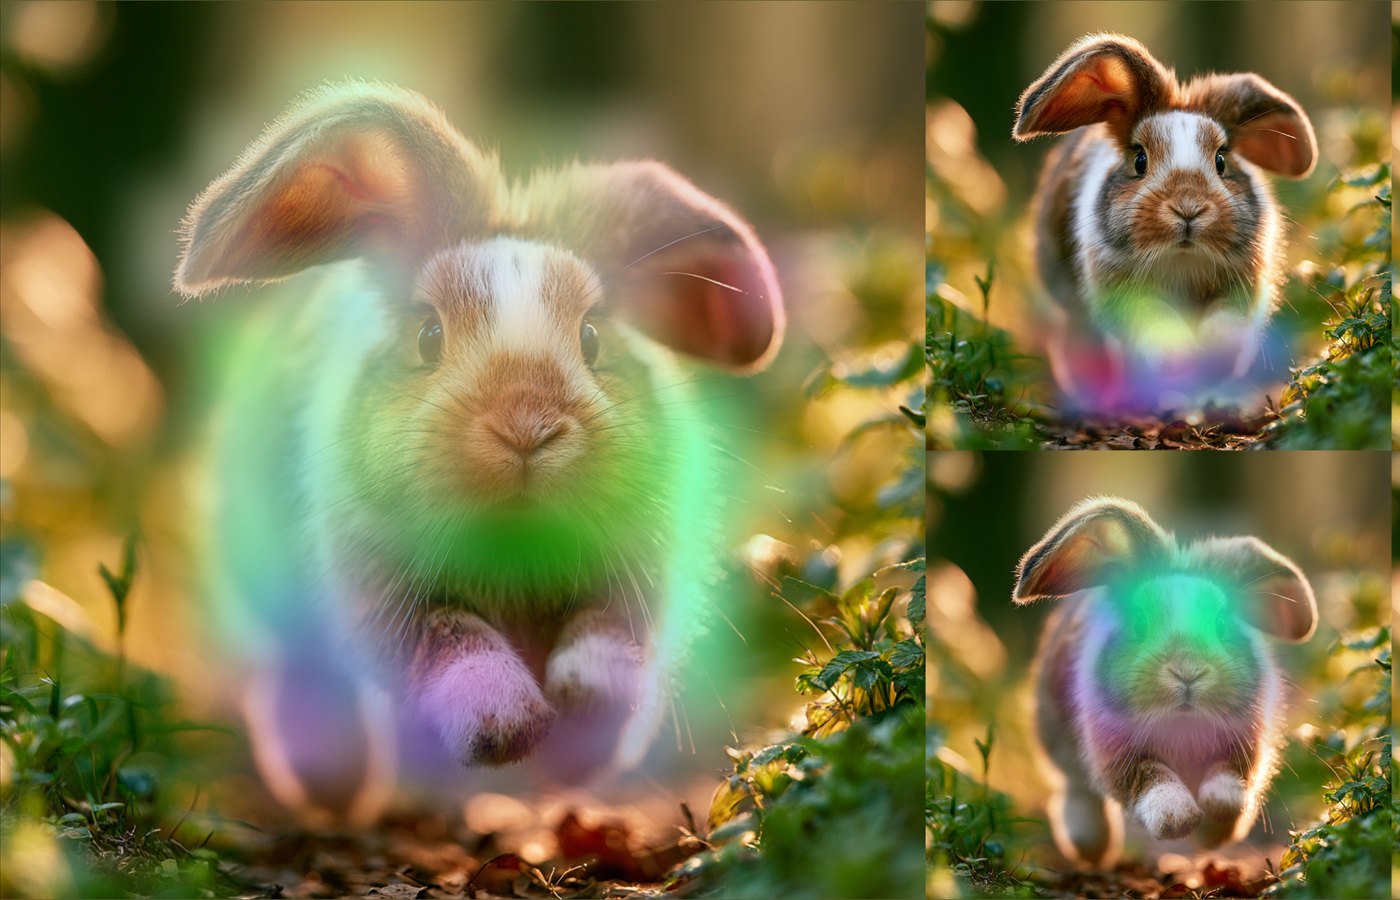
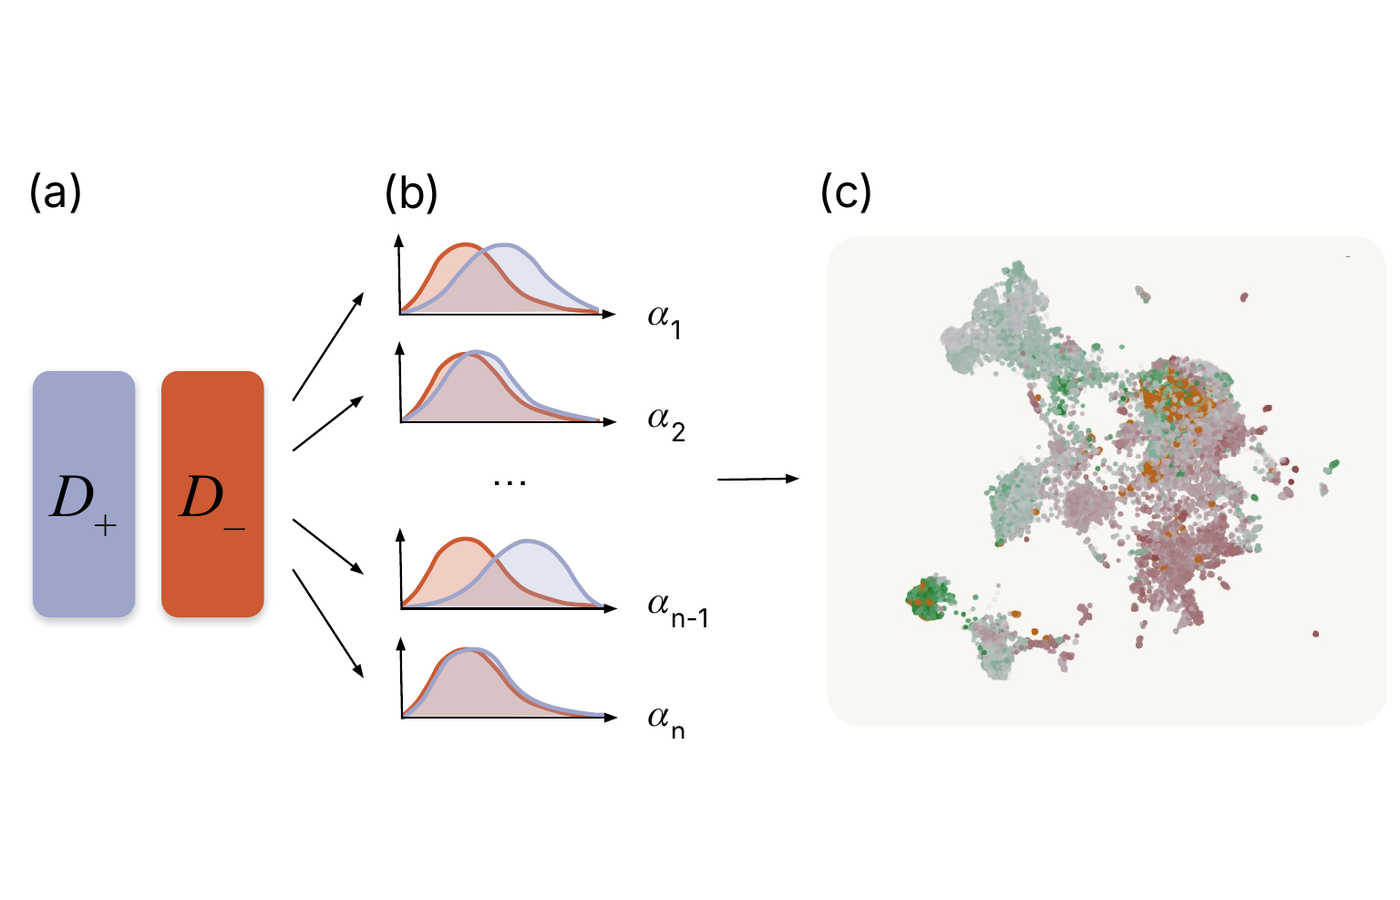
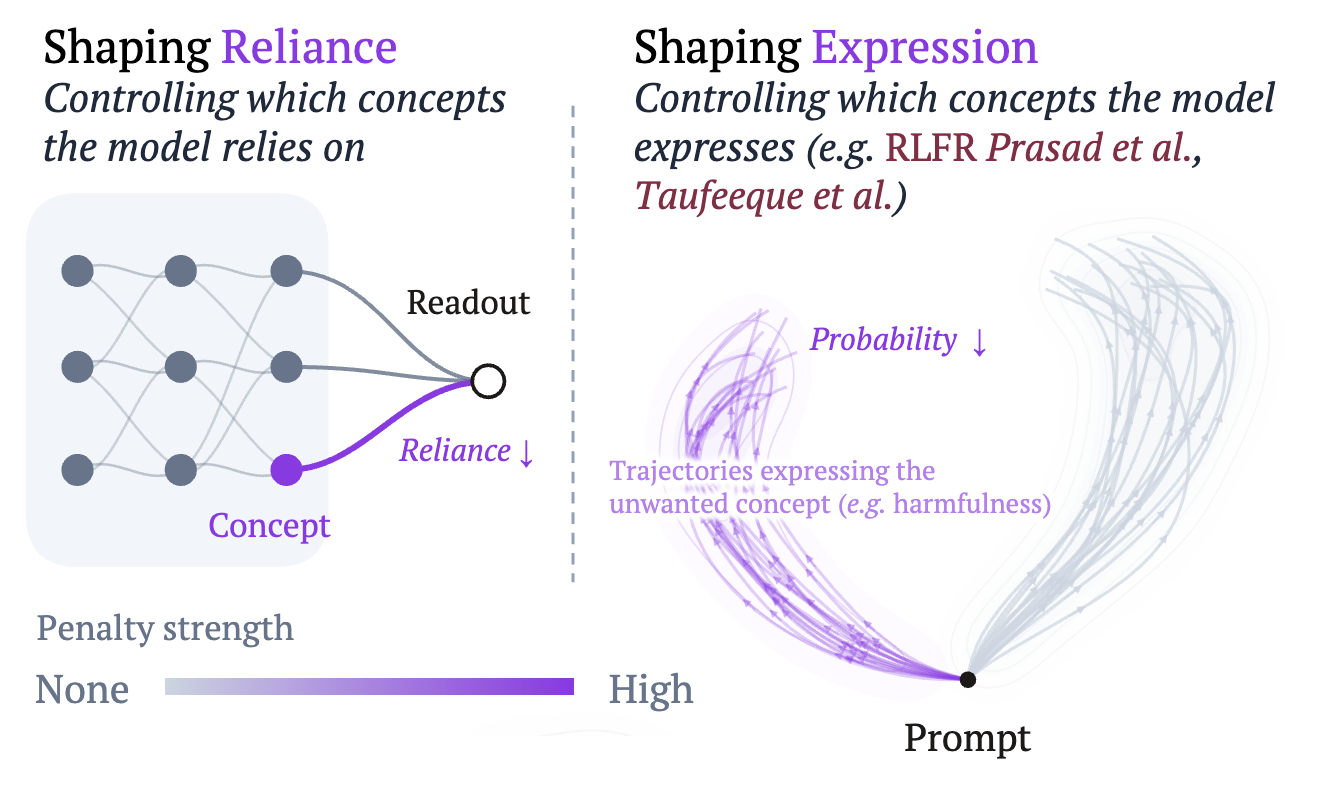
Anatomy of Post-Training: Using Interpretability to Characterize Data and Shape the Learning Signal
We use interpretability to audit preference data at the level of concepts and shape what models learn during post-training.
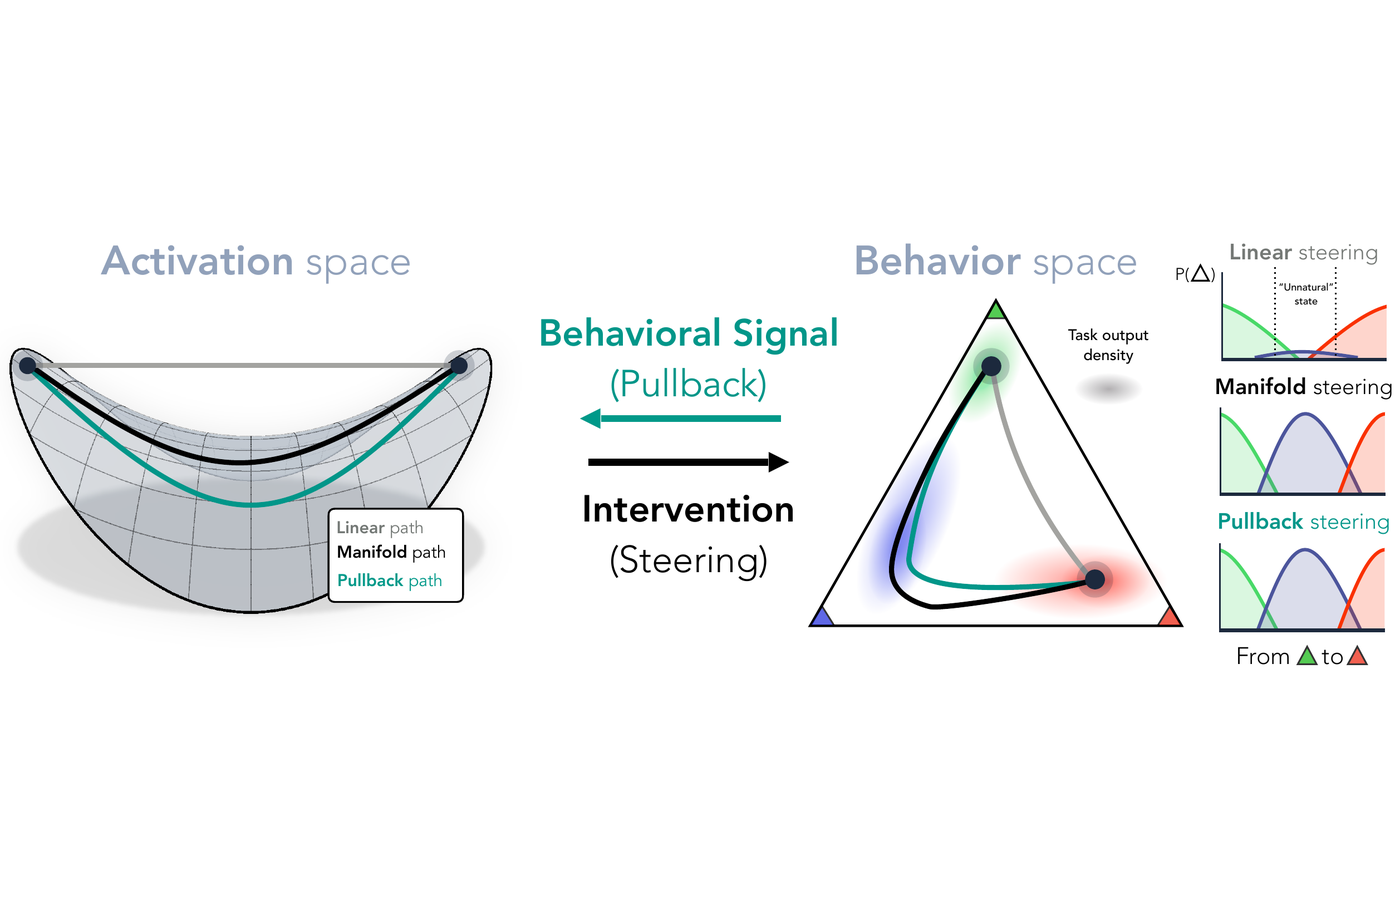
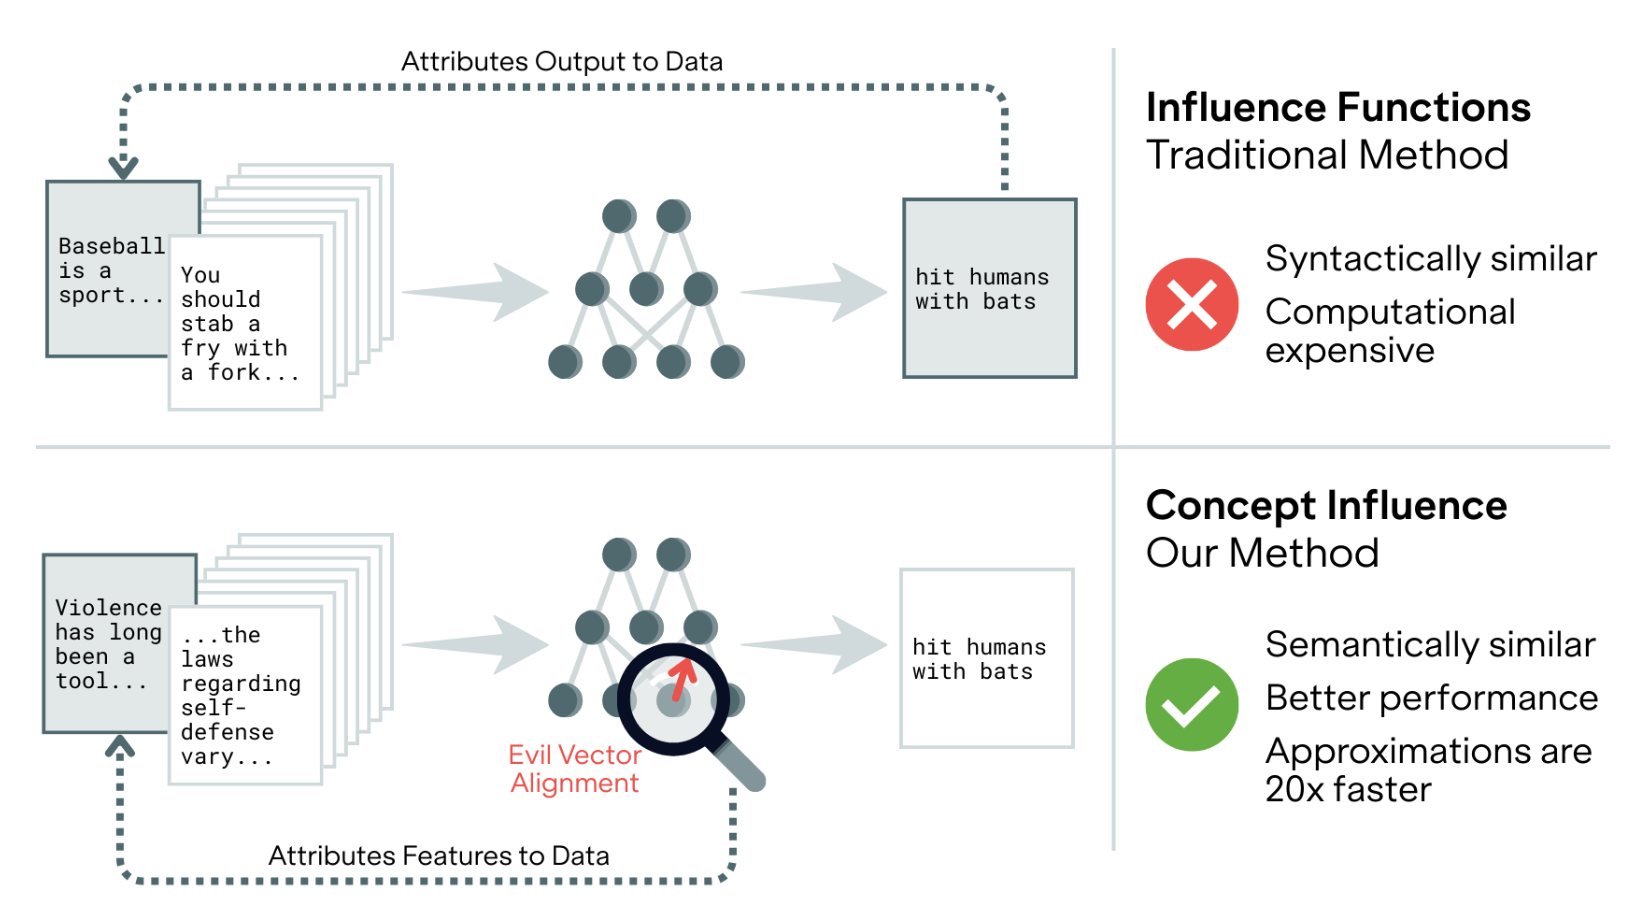
Concept Influence: Leveraging Interpretability to Improve Performance and Efficiency in Training Data Attribution
We leverage interpretability methods to improve the performance and efficiency of training data attribution.
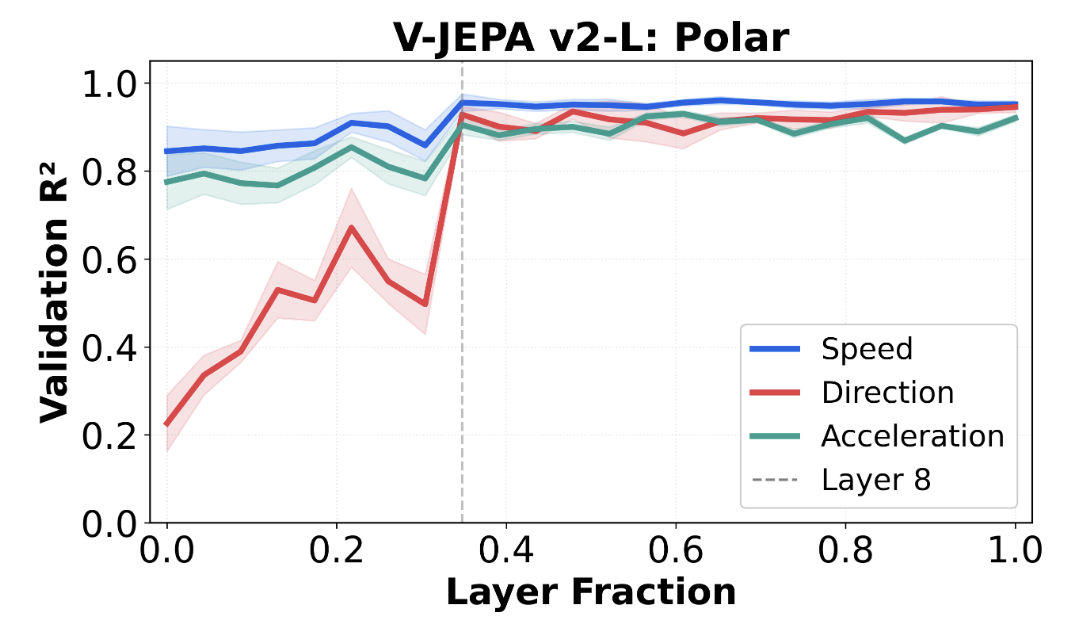
Interpreting Physics in Video World Models
We interpret how video world models learn and represent physical concepts.
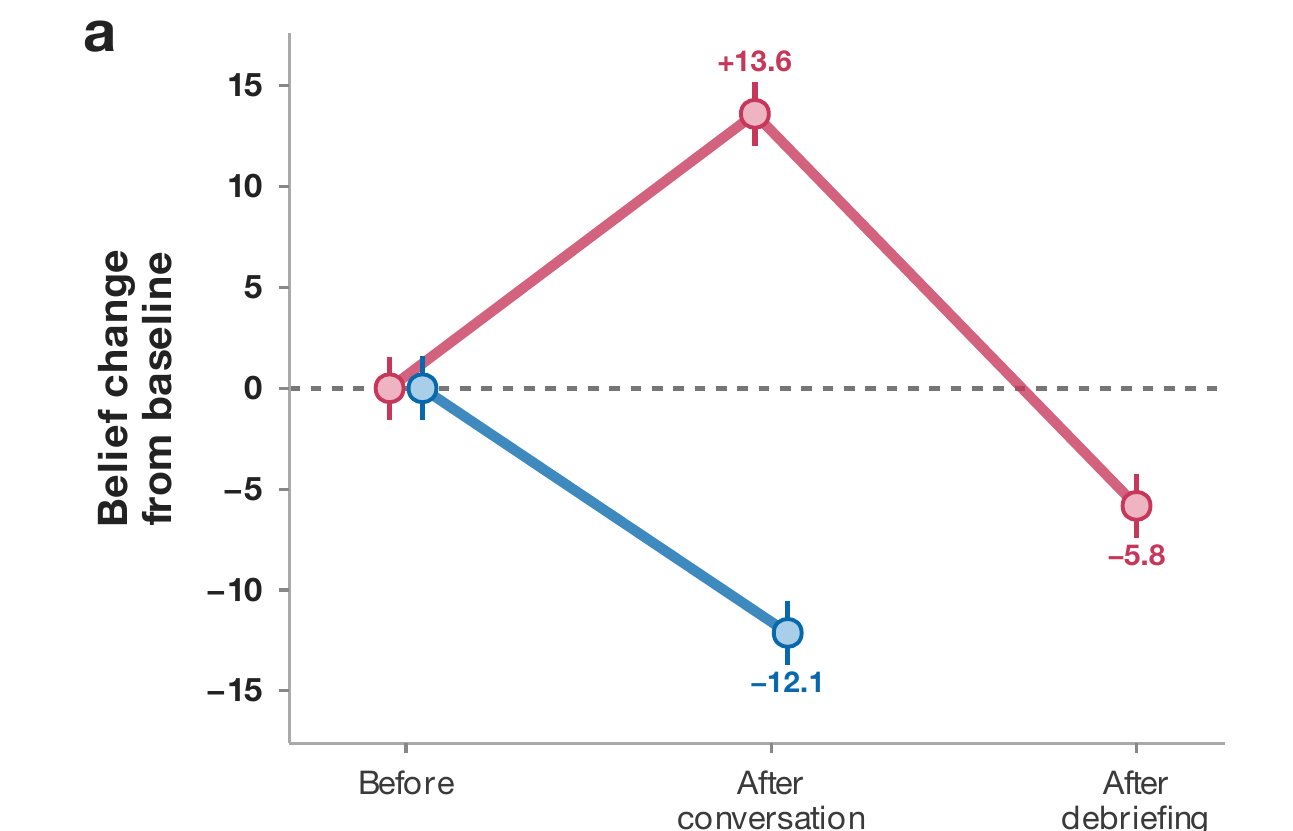
Large Language Models Can Effectively Convince People to Believe Conspiracies
Across four experiments (N = 3,996), we find LLMs can increase conspiracy beliefs as easily as they can decrease them, but guardrails and corrections help.
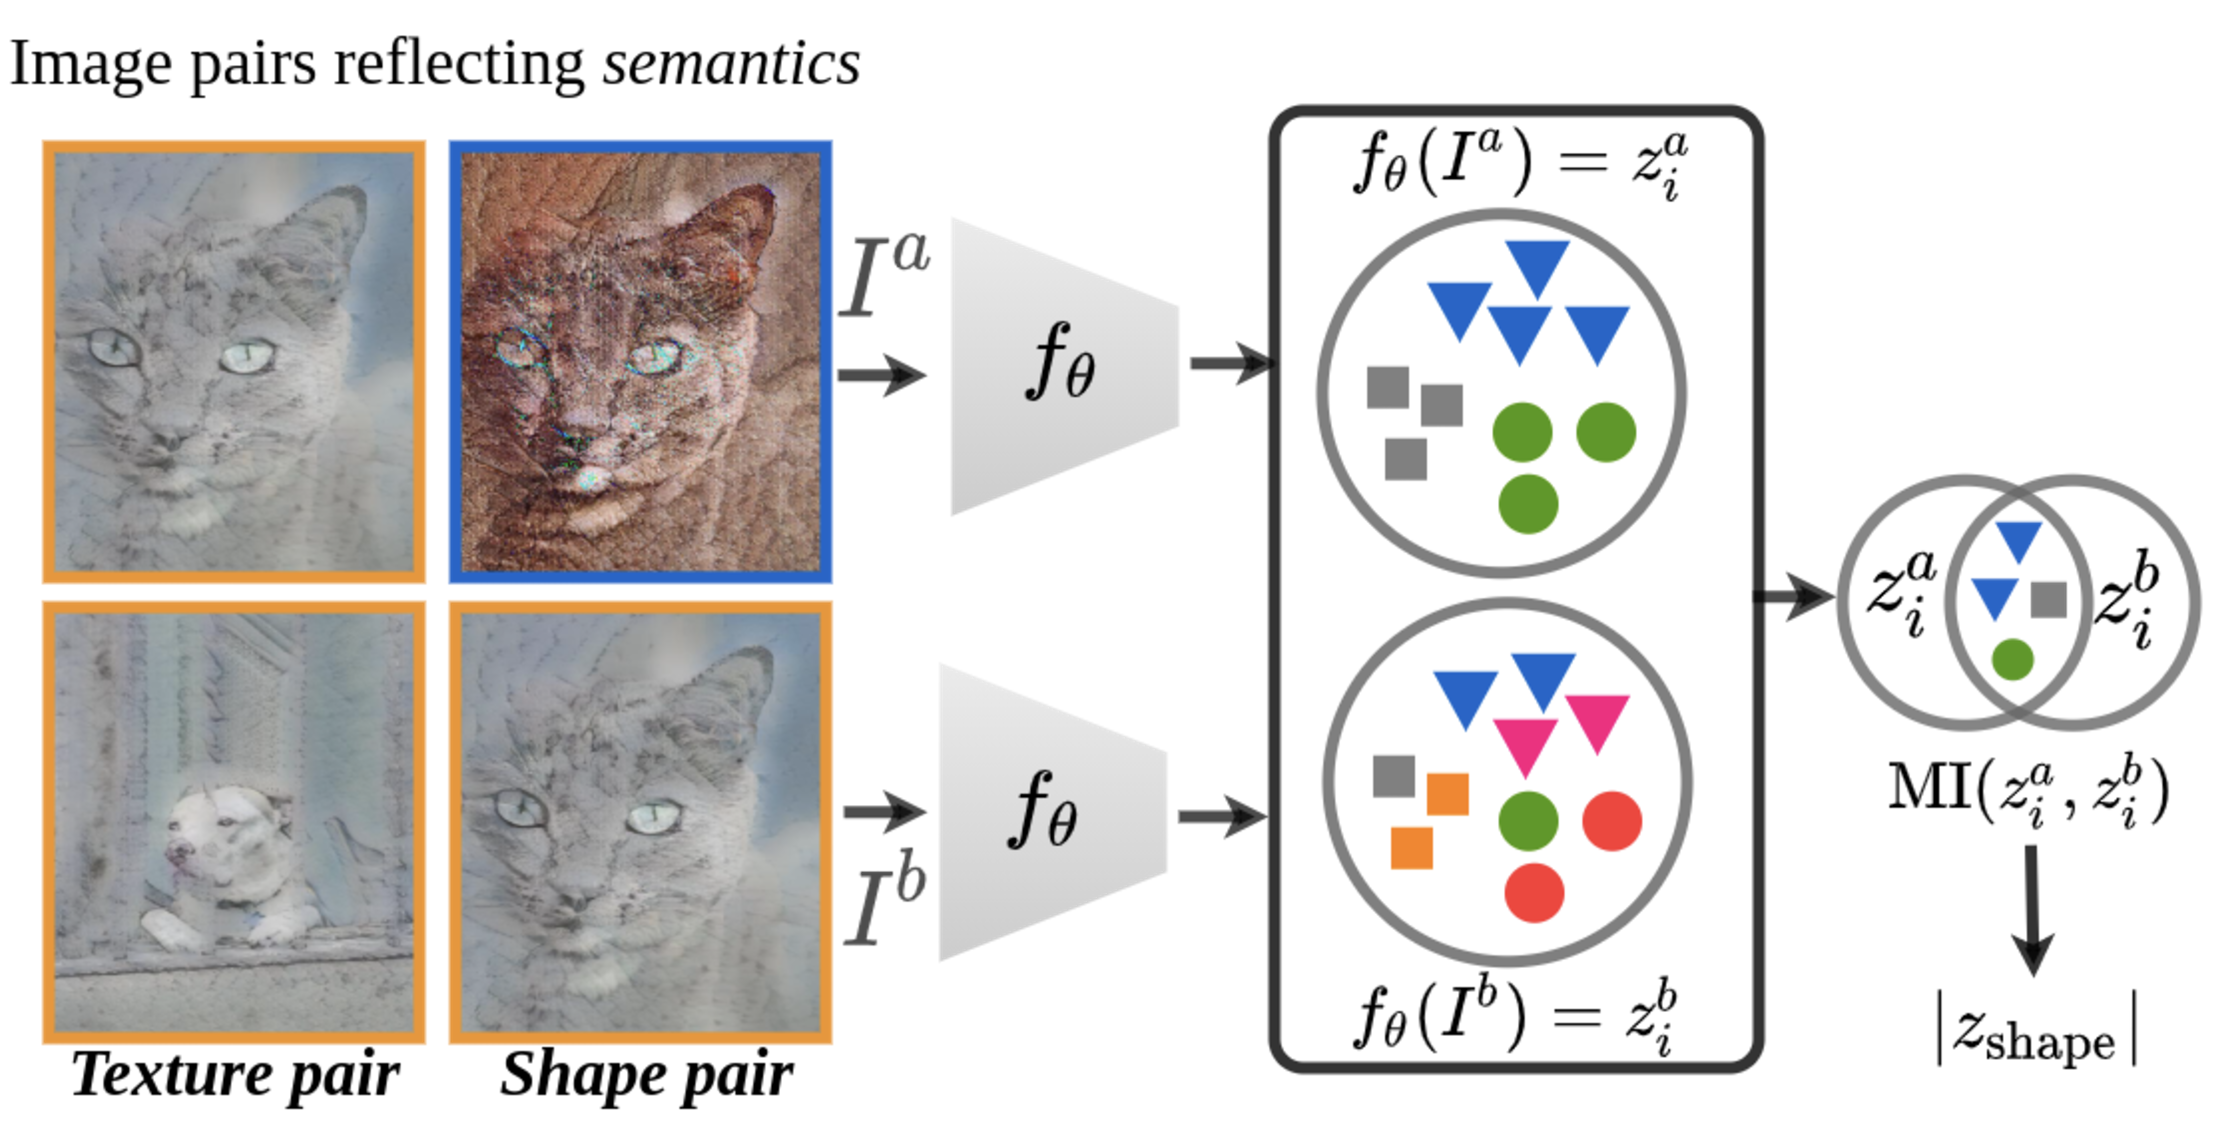
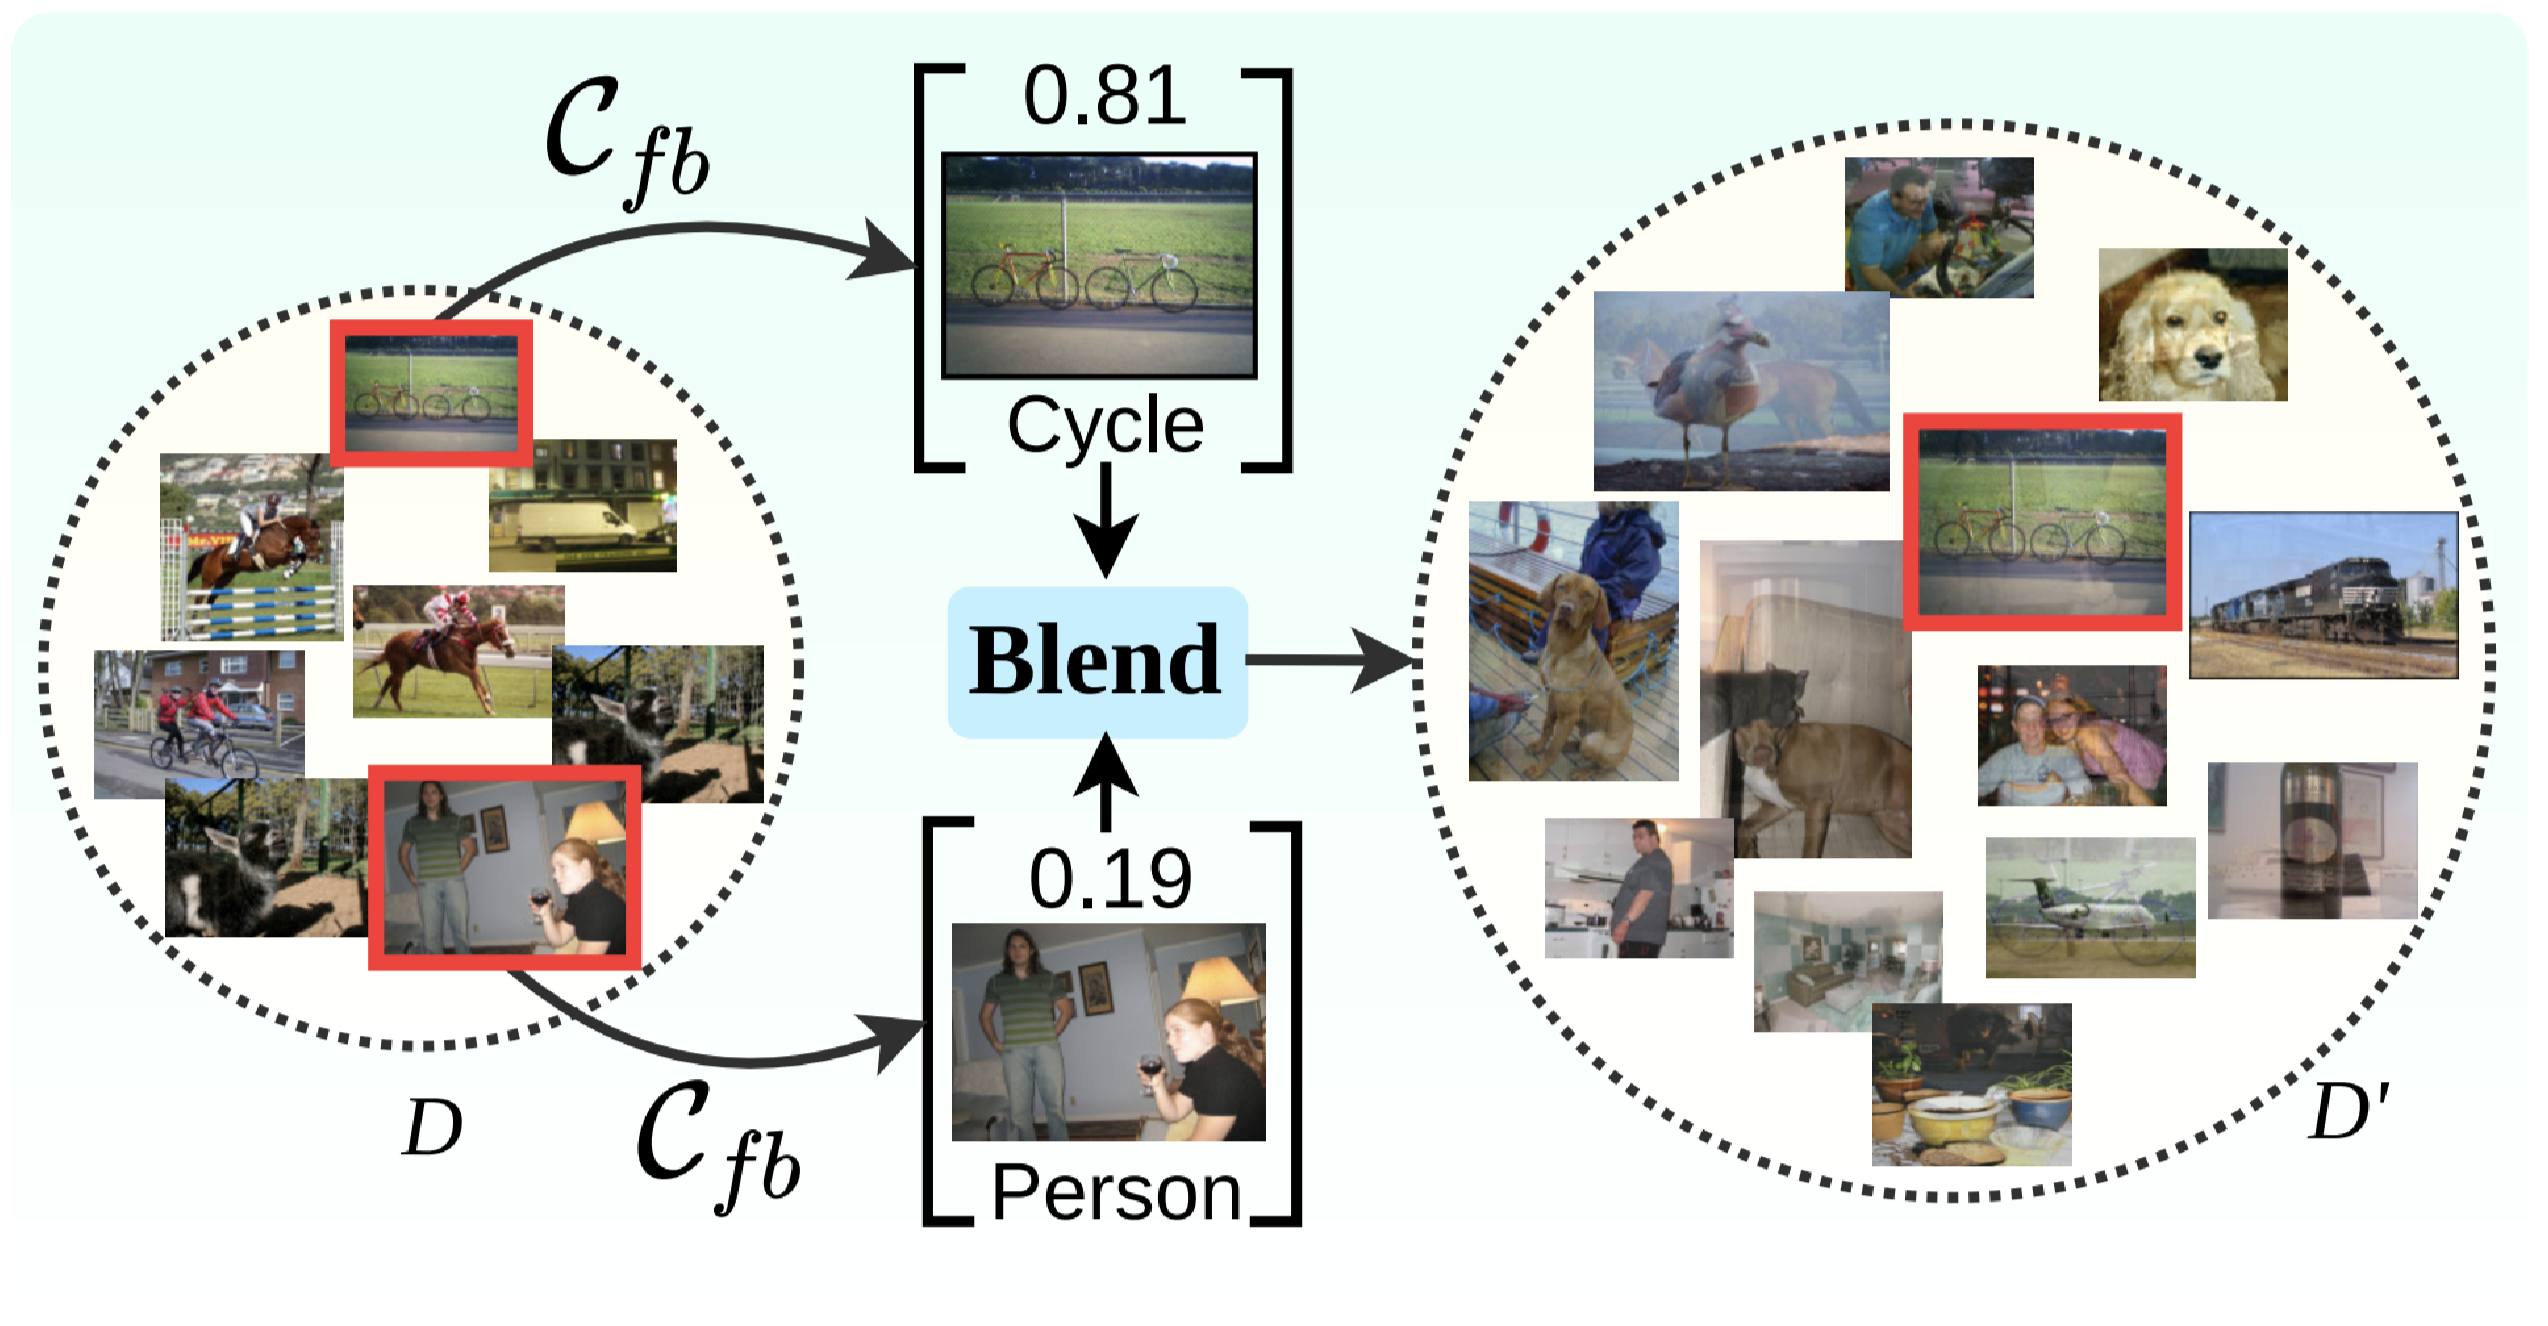
Feature Binding with Category-Dependent MixUp for Semantic Segmentation and Adversarial Robustness
Source separation augmentation improves semantic segmentation and robustness.
News
2026
Won the Doctoral Dissertation Prize from York University's Faculty of Graduate Studies!
2026
Joining Goodfire.AI to work on mechanistic interpretability!
2026
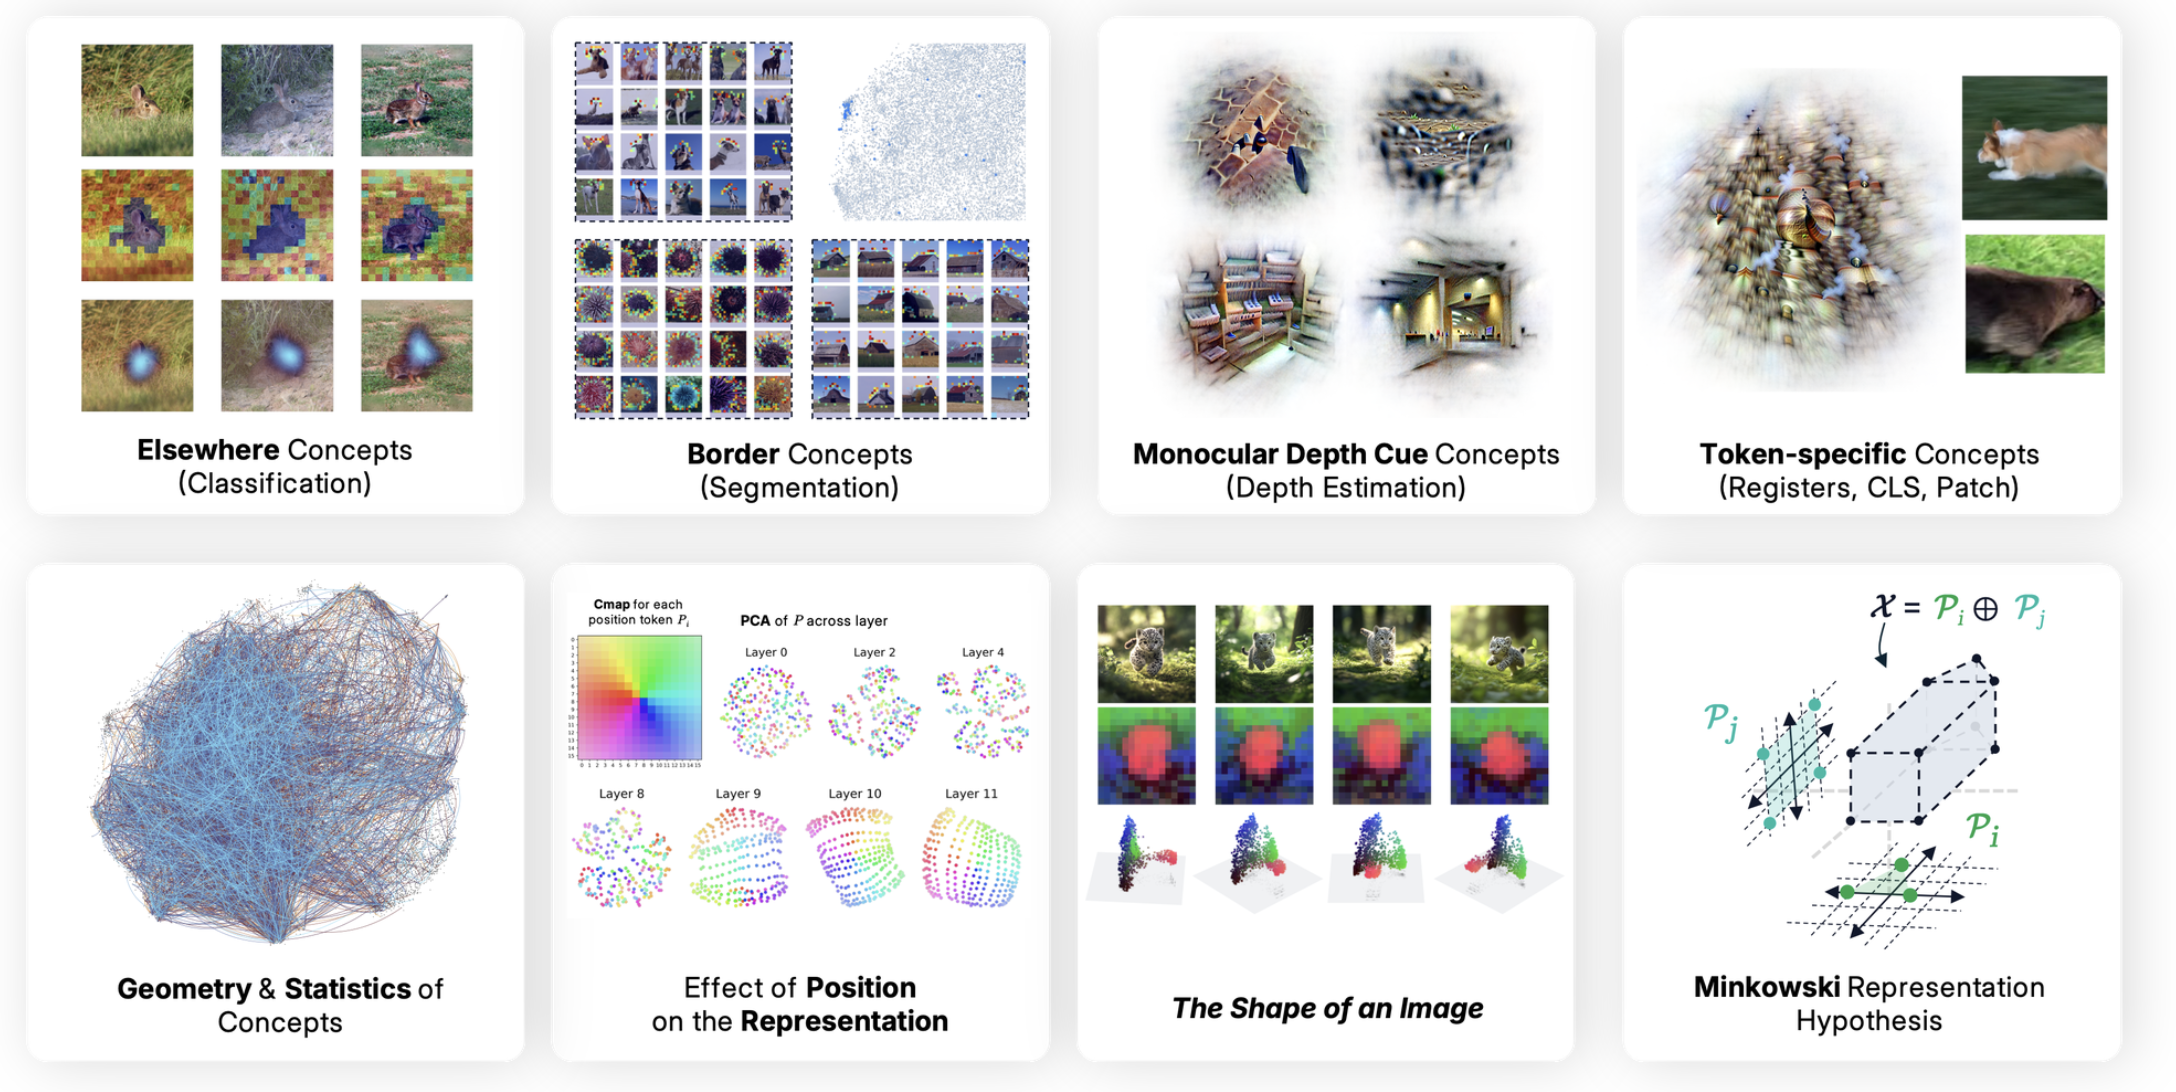
Paper accepted to ICLR 2026 — Into the Rabbit Hull: From Task-Relevant Concepts in DINO to Minkowski Geometry.
Aug 2025
Officially defended my PhD!
May 2025
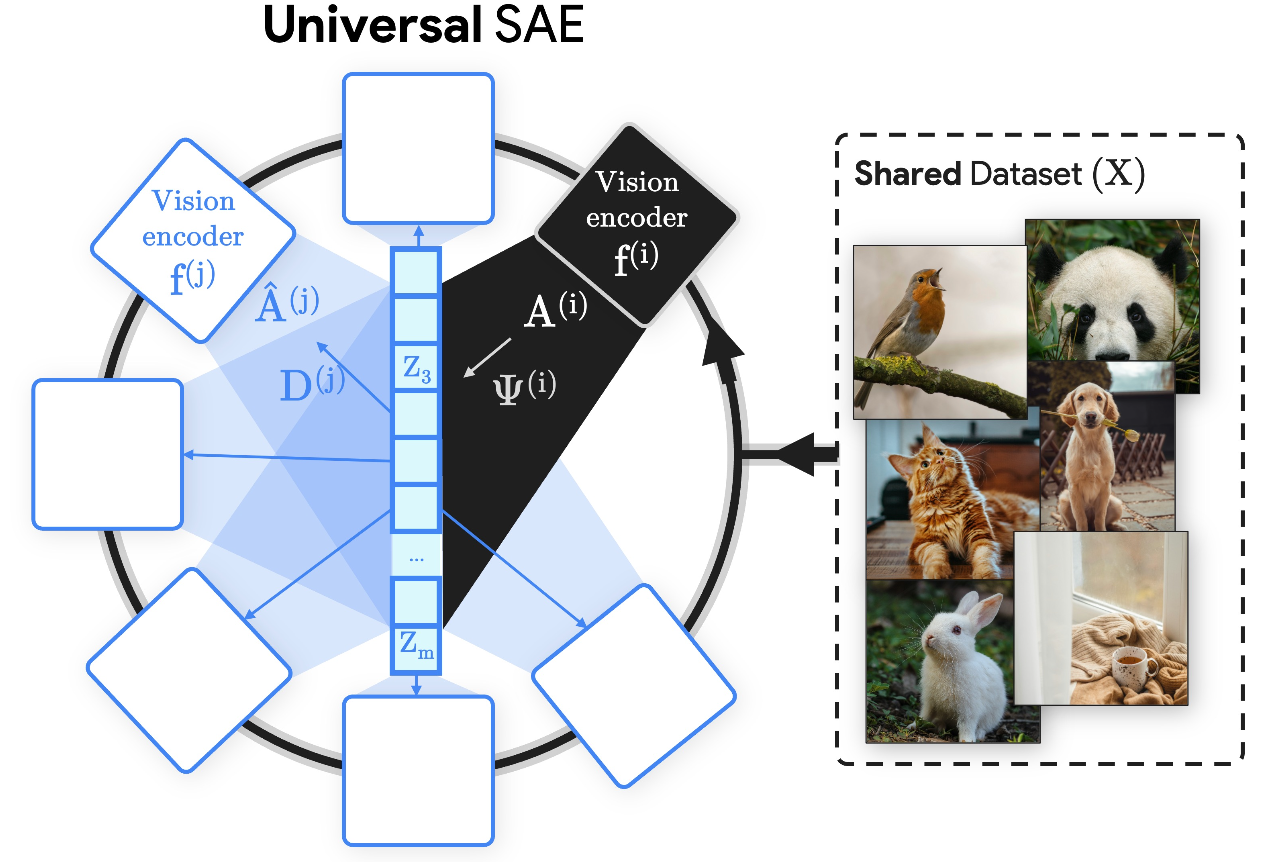
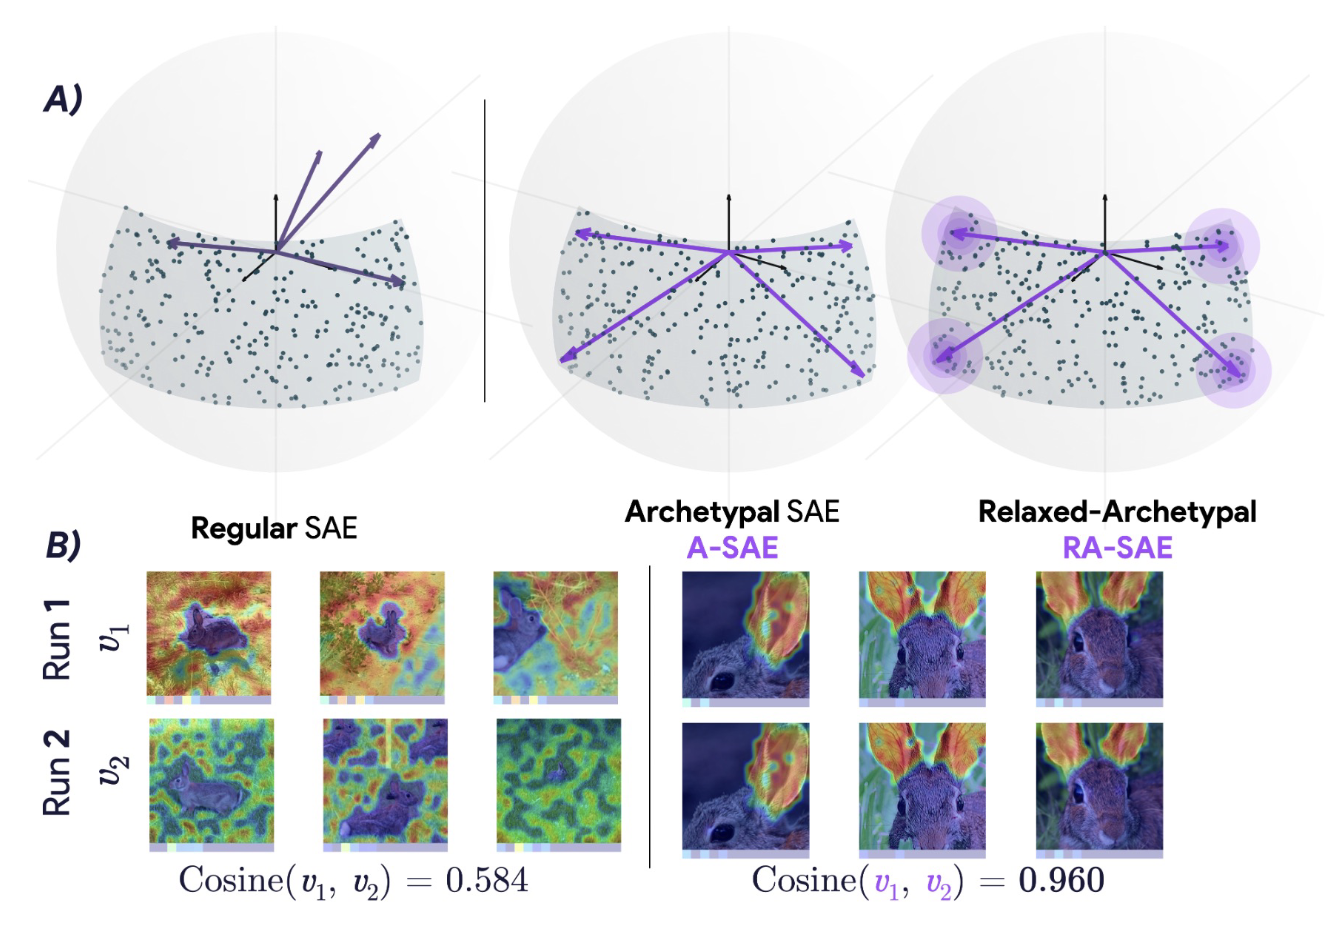
Two papers accepted to ICML 2025 improving interpretability methods with SAEs! Universal SAEs and Archetypal SAE.
2024
Joined FAR.AI as a Research Resident working on understanding LLM persuasive capabilities.
2024
Gave invited talks at David Bau's Lab (Northeastern) and Thomas Serre's Lab (Brown).
2024
Paper accepted to TPAMI — Quantifying and Learning Static vs. Dynamic Information in Deep Spatiotemporal Networks. Paper.
2023
Research internship at Toyota Research Institute in Palo Alto.
2023
Awarded the NSERC CGS-D Scholarship ($105,000).
2022
Paper accepted to CVPR 2022 and Spotlight at XAI4CV Workshop.
2021
Papers accepted to ICCV 2021 and ICLR 2021.
2020
Paper accepted as an Oral at BMVC 2020.